D · The Data Platform on One Page
This page puts Steep’s whole data platform on one map, and then names each piece in open-source, AWS and Alibaba Cloud terms. Use the map to see where a tool sits; use the table to turn a job ad’s list of products back into the chapters of this book.
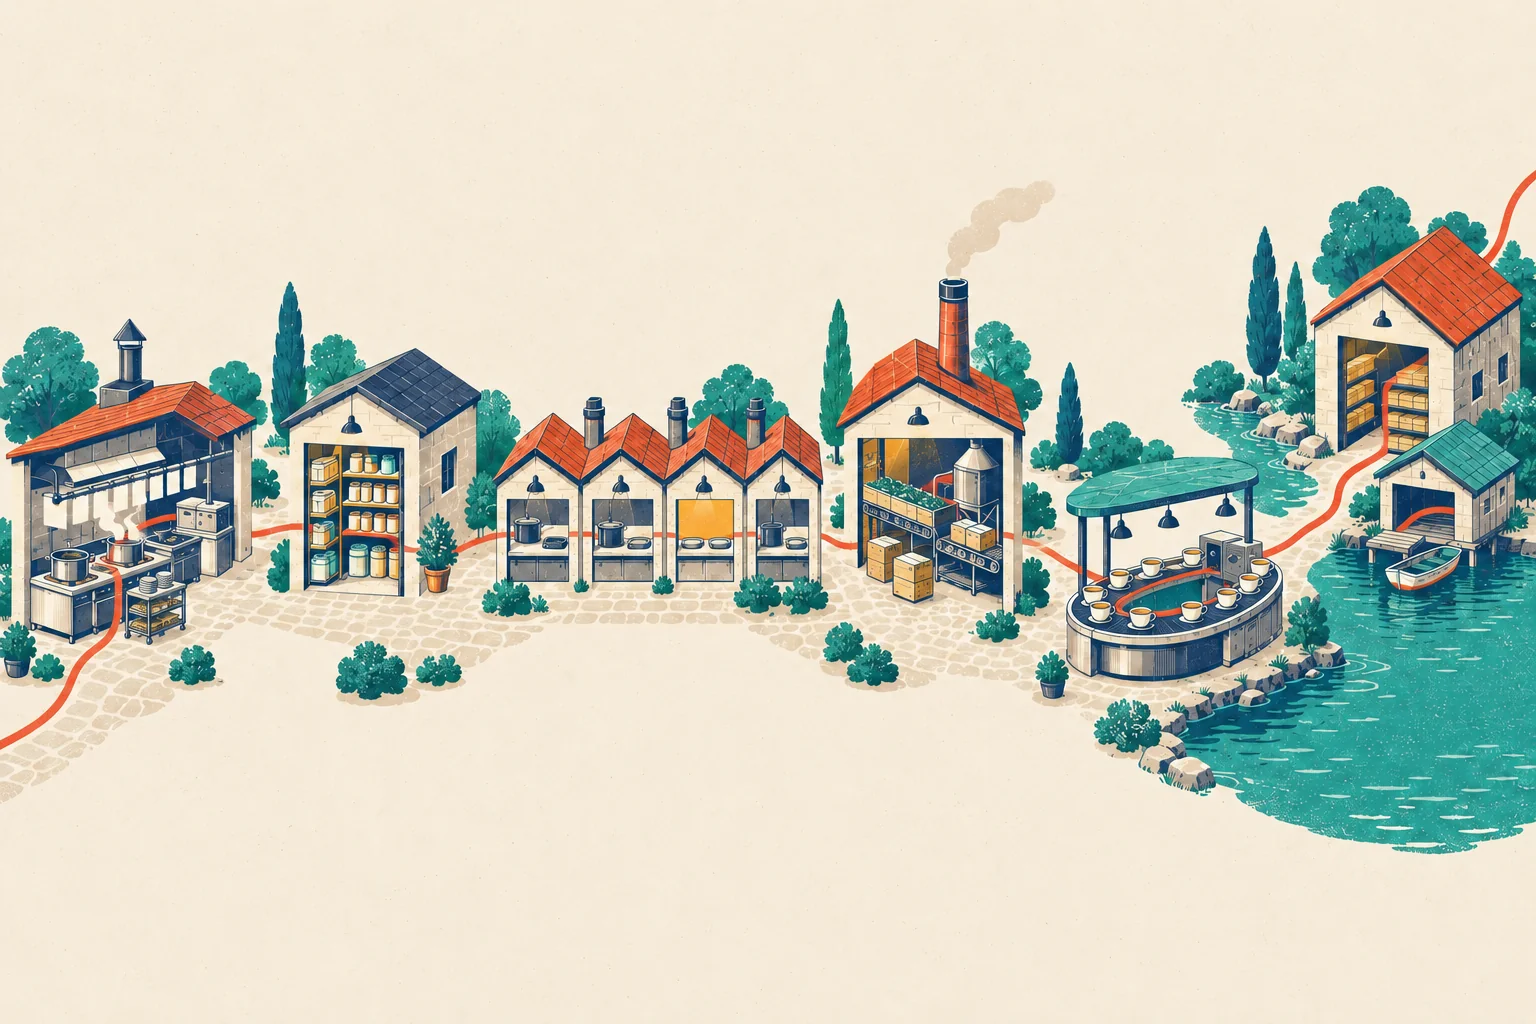
The town of Part II. From the left: the kitchen with the ticket rail (Kafka, Chapter 8); the pantry with its shelves of jars (storage, Chapter 9); four small kitchens side by side, one lit brighter than the rest (Hive and Spark, Chapter 10); the tea factory (batch pipelines, Chapter 13); the conveyor-belt tea bar (streaming, Chapter 14); the boathouse on the lake (the lakehouse, Chapter 11); and the warehouse with its shelves (Chapter 12). The red path is the road of one order.
The map
Each box names one job and the chapter that teaches it. On a computer, the map reads from left to right; on a phone, from top to bottom. The list under the map links to every chapter.
Steep’s data platform. The tomato line follows order A1024, Mia’s oolong milk tea, from her phone to the warehouse summaries (DWS). The CEO dashboard counts events, so the order never reached it.
Reading the map: the road of one order
- Apps and web (Chapter 7). Mia paid in the iOS app. The app sent its events, but not
order_completed: that one event was lost here, in the app itself (Chapter 15). - The orders database (Chapter 7, Chapter 9). The order service saved order
A1024as one row in MySQL. For orders and money, this is the system of record. - The nightly copy and change data capture (Chapter 13, Chapter 7). Once a night, Steep copies the orders table into the lake: that is how the row of
A1024reached the lake. MySQL also wrote every change to its binlog: the insert at payment, then the update tocompleted. A CDC tool such as Debezium reads the binlog and passes each change to Kafka, and Steep keeps a copy of the binlog in the lake (cdc_orders_binlog). - Kafka (Chapter 8). Events and changes wait in order, in partitions, for a set time (seven days by default), whether or not anyone has read them. Each reader keeps its own place, its offset.
- The data lake (Chapter 9, Chapter 10, Chapter 11). Parquet files in
dt=folders, on HDFS or object storage. A catalog gives the folders table names. Steep’s tables are plain Hive tables; a table format, drawn dashed, would add commits, updates and time travel. - Batch compute and the scheduler (Chapter 10, Chapter 13). Every night, the scheduler starts Spark jobs in the order of their dependencies, one partition per day.
- The warehouse layers (Chapter 12). ODS keeps raw copies, DWD cleans them, DWS summarises, and ADS serves one report each.
A1024is in DWD and DWS. The CEO dashboard’s ADS table countsorder_completedevents, so the order stops there. - Query engines and dashboards (Chapter 11, Chapter 5). The CEO dashboard never counted
A1024. Reports built on the orders, such as finance’s, did. - The stream path (Chapter 14). Flink reads the same Kafka topics and answers within seconds: alerts now, exact numbers later from the batch path.
- Quality and lineage (Chapter 15). Tests compare the steps with each other, every day, and lineage says what else a broken table touches.
The same jobs, by their product names
Job ads list products, not jobs. Find the product in the table, read the job it does, and go to the chapter. Names change, and a product can be retired; the job matters more than the brand. For example, Amazon QuickSight was renamed Amazon Quick Sight (two words), a feature of Amazon Quick, and MaxCompute was once called ODPS. Products marked “closest match” do a similar job in a different way.
| Job | What it does | Open source | AWS | Alibaba Cloud | Ch |
|---|---|---|---|---|---|
| Event collection | Records what people do in an app or on a website, and sends it to a server | Snowplow; RudderStack ‡ | No single product: Guidance for Clickstream Analytics on AWS (closest match) | Quick Tracking; Simple Log Service (SLS) web tracking | 7 |
| Change data capture | Reads a database’s change log (the binlog) and passes on every change | Debezium; Apache Flink CDC; Canal | AWS Database Migration Service (AWS DMS) | Data Transmission Service (DTS) | 7 |
| Data integration and loading | Copies data from one system into another on a schedule or all the time, such as the nightly copy of the orders table, or Kafka into the lake | Kafka Connect; DataX; Apache SeaTunnel | AWS Glue; Amazon Data Firehose | DataWorks Data Integration | 8, 13 |
| Message queue | Keeps events in order, so that many readers can read them, each at its own pace | Apache Kafka | Amazon Managed Streaming for Apache Kafka (Amazon MSK); Amazon Kinesis Data Streams (closest match) | ApsaraMQ for Kafka; DataHub (closest match) | 8 |
| Stream processing | Computes results from events as they arrive, within seconds | Apache Flink | Amazon Managed Service for Apache Flink | Realtime Compute for Apache Flink | 14 |
| Storage | Keeps the files, cheaply and with several copies | HDFS | Amazon S3 | Object Storage Service (OSS); OSS-HDFS | 9, 10 |
| Table format | Turns folders of files into tables with commits, updates and time travel | Apache Iceberg; Delta Lake; Apache Hudi; Apache Paimon | Amazon S3 Tables (Iceberg) | Data Lake Formation (DLF), with Paimon tables | 11 |
| Metadata catalog | Knows each table’s columns, files and partitions, so that engines can find them | Hive Metastore; Apache Polaris; Unity Catalog; Apache Gravitino | AWS Glue Data Catalog | Data Lake Formation (DLF) | 10, 11 |
| Batch compute | Runs big jobs over many machines, usually once a night | Apache Spark; Apache Hive | Amazon EMR; AWS Glue | E-MapReduce (EMR); MaxCompute | 10 |
| SQL transformations | Builds the warehouse layers from SQL files, in the order of their dependencies, with tests | dbt (open-source dbt Core) | No product of its own: dbt on Amazon Redshift or Amazon Athena | DataWorks with MaxCompute SQL | 12, 15 |
| SQL on files | Runs SQL on files where they lie, and keeps no data of its own | Trino; Presto | Amazon Athena | E-MapReduce (EMR) with Trino | 11 |
| Scheduler | Starts jobs in the order of their dependencies, on time, and retries failures | Apache Airflow; Apache DolphinScheduler | Amazon Managed Workflows for Apache Airflow (Amazon MWAA) | DataWorks | 13 |
| Warehouse and OLAP database | Keeps its own copy of the data and answers analysis queries fast | ClickHouse; Apache Doris; StarRocks | Amazon Redshift | MaxCompute; Hologres; AnalyticDB for MySQL; EMR Serverless StarRocks | 11, 12 |
| BI dashboards | Charts and dashboards for the people who decide | Apache Superset; Metabase | Amazon Quick Sight | Quick BI | 5 |
| Data quality | Tests the data every day and alerts an owner when a test fails | dbt data tests; Great Expectations (GX Core); Deequ | AWS Glue Data Quality | DataWorks Data Quality | 15 |
| Lineage and metadata | Shows which table is built from which, what it means and who owns it | OpenLineage (with Marquez); DataHub; Apache Atlas | Amazon SageMaker Catalog (built on Amazon DataZone) | DataWorks Data Map | 12, 15 |
Notes on the table:
- Closest match. Amazon Kinesis Data Streams and Alibaba Cloud DataHub are streaming services of their own, not Kafka. AWS has no single event-collection product: its Guidance for Clickstream Analytics on AWS is a ready-made design with app SDKs: small code libraries inside the app that send its events into AWS services.
- ‡ Source-available, not open source. Snowplow’s trackers are open source, but its collector and pipeline now use the Snowplow Limited Use License. RudderStack’s server uses the Elastic License 2.0, and so does Soda Core, a data-quality tool. Read the licence before you build on any of them.
- One product, several jobs. DataWorks loads data, runs SQL jobs on a schedule, tests data quality and keeps lineage. MaxCompute is both the warehouse and its compute engine. Data Lake Formation is a catalog and managed table storage. DataX is the open-source version of DataWorks’ data integration. In real platforms, one product often does several of these jobs. The map shows the jobs, not the products that vendors sell.
- Steep’s own stack. Steep uses the open-source pieces named in the chapters: MySQL, Kafka, Parquet files with a Hive metastore (plain Hive tables, no table format yet; Chapter 11), Spark and a scheduler. DuckDB is the engine inside this book.